 LiveEdTech · Audio description
NexDescribe
Human-quality audio description at scale: bulk ingest, time-coded writing, QC and approvals, and TTS mixed under the program audio, from the pipeline that described 50,000 videos in seven months.
Overview
Audio description from script to mixed track.
Audio description at volume is a scheduling problem as much as a creative one. Every video needs its gaps found, a script written to fit them, a voice recorded and a track mixed — and the whole thing has to be trackable when there are tens of thousands of videos and a fixed deadline.
NexDescribe is the system behind that work. It detects candidate description gaps in the audio, gives describers a timecoded scripting view with the fit constraint visible, and carries the script through voicing, mixing and delivery with status per asset. It is the tooling that let one program take more than 50,000 videos to WCAG conformance in seven months.
The film · 0:30
NexDescribe in 30 seconds
Music only, no voiceover. Everything the film shows is set out on this page.
From upload to published mix
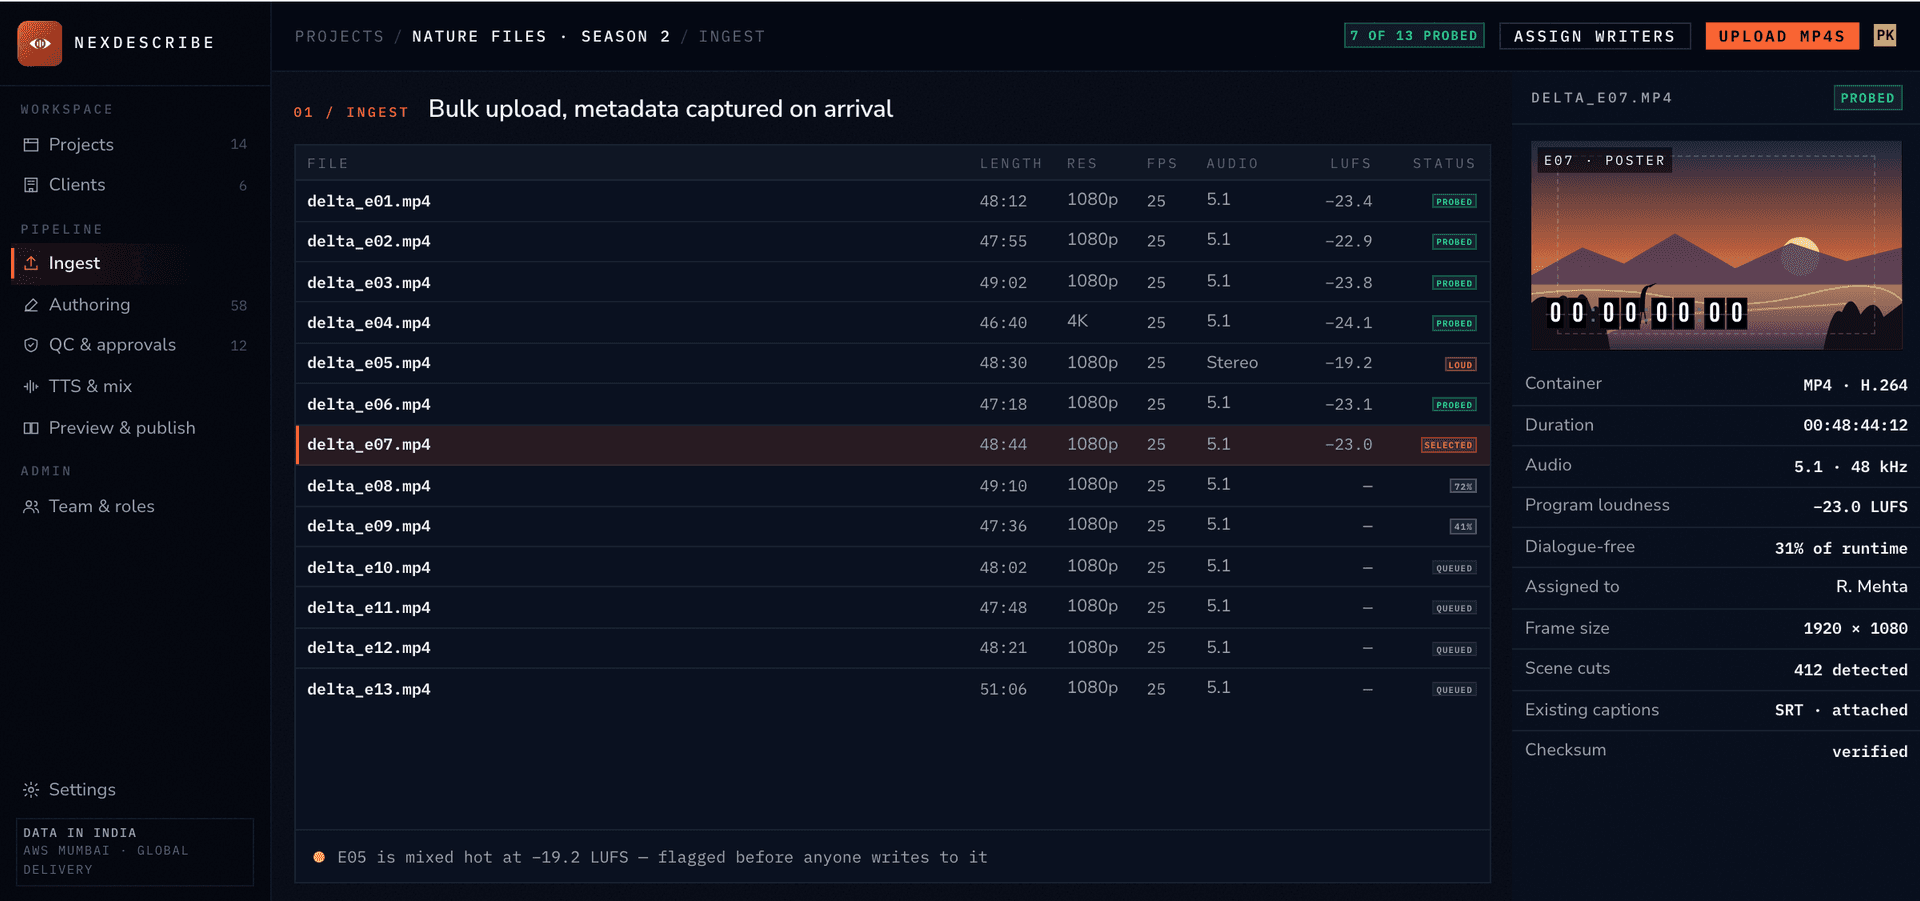
- 01 · Bulk ingest
A whole season in, and every file measured before anyone writes a word.
Upload MP4s in bulk; duration, frame rate, audio layout and program loudness are captured on arrival for every step after.
- Bulk MP4 upload
- Duration, frame rate and audio layout captured
- Loudness measured on arrival
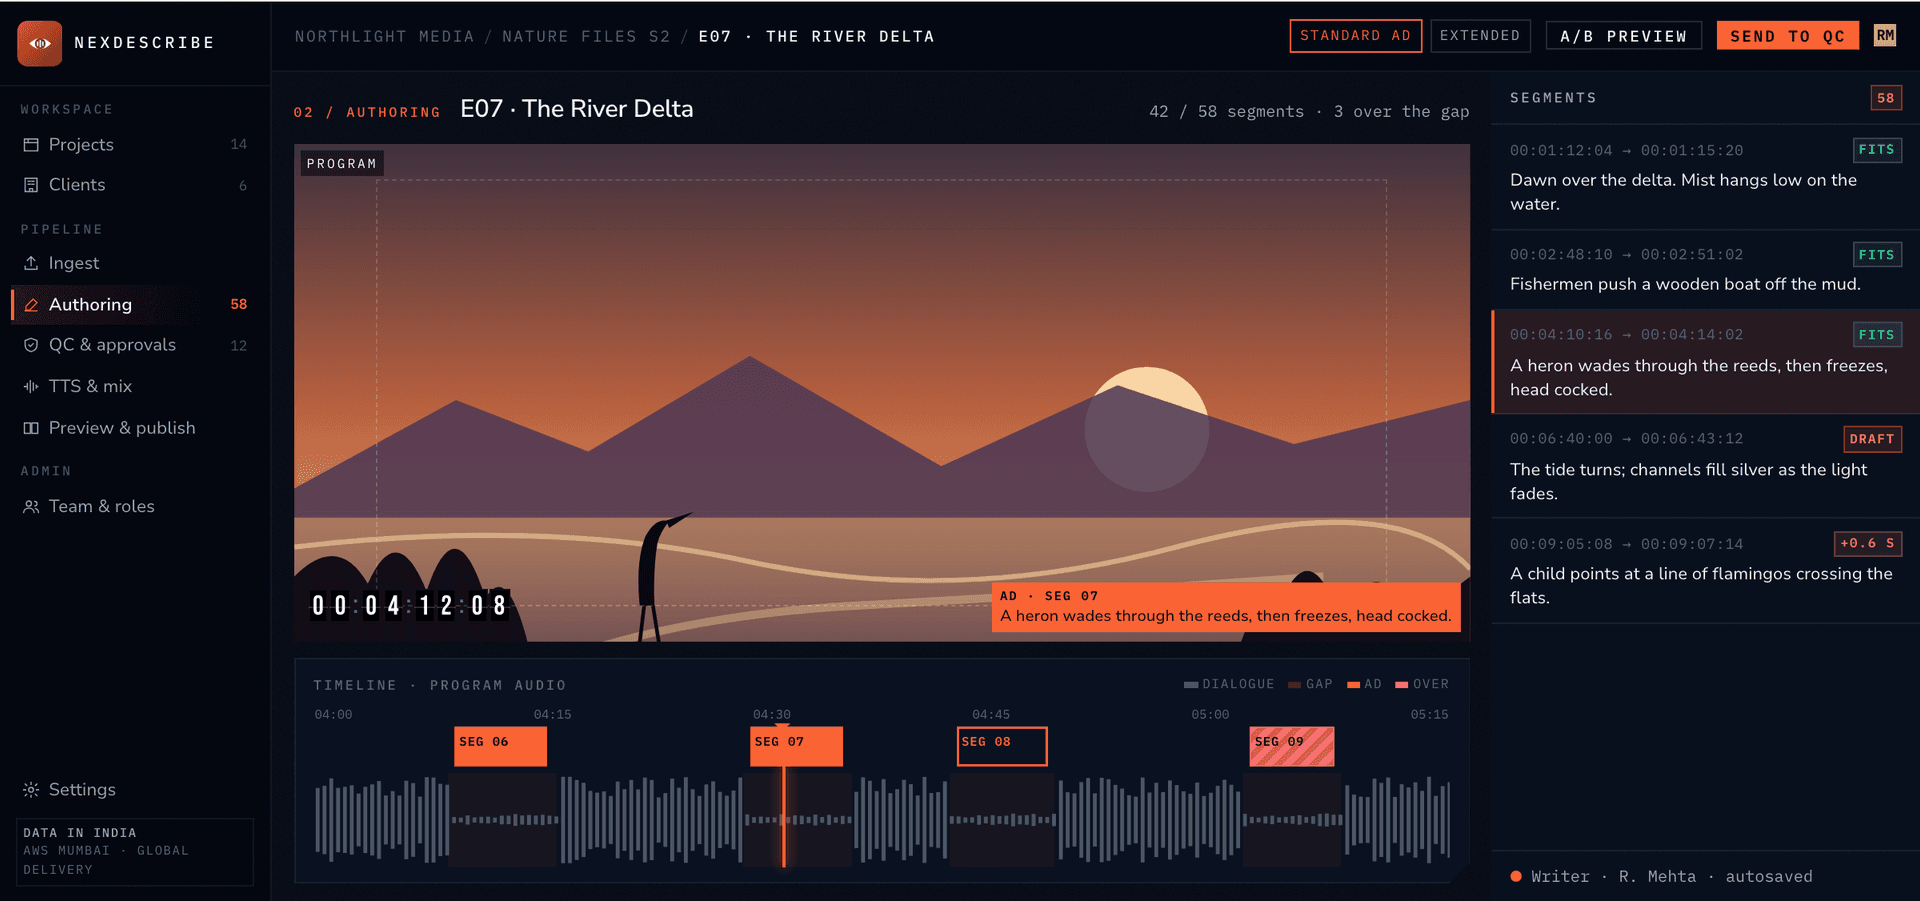
- 02 · Time-coded AD writing
Write to the frame, and know it fits before you move on.
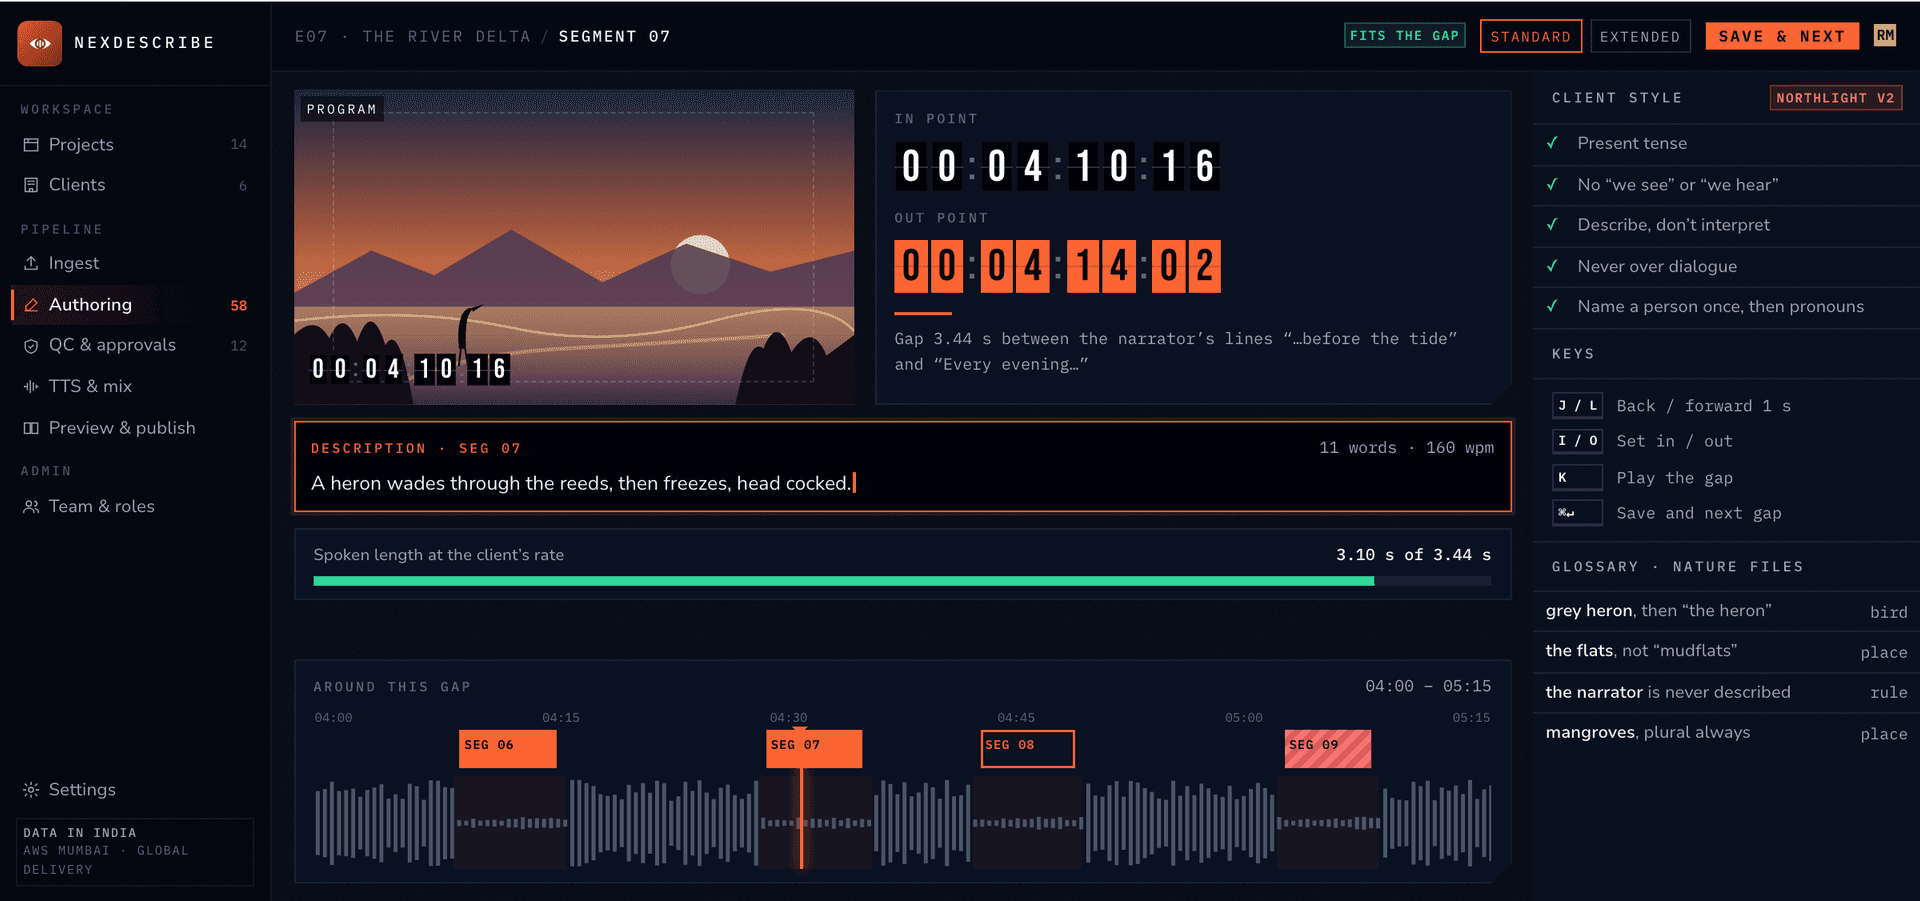
Writers script to the timeline, with each segment’s in and out point, word count and fit against the gap shown as they type.
- In and out points per segment
- Fit against the gap shown as you type
- Word count per segment
- 03 · QC and approvals
Checks first, then people, then a signature.
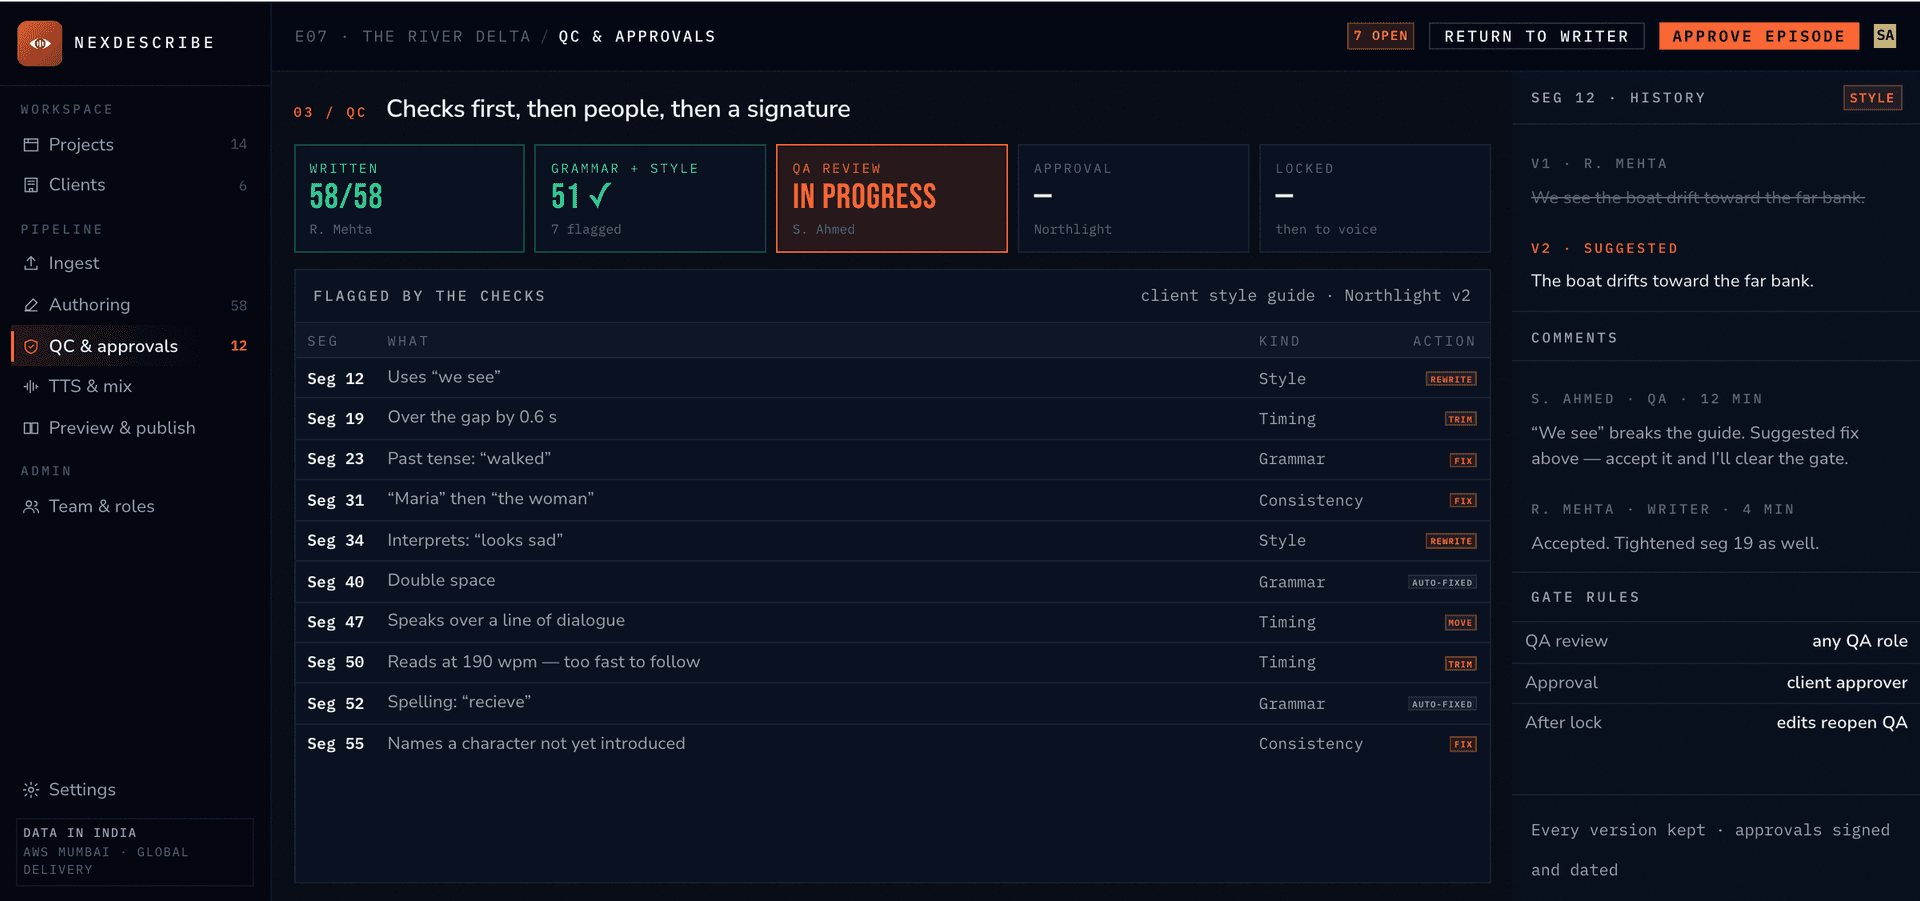
Grammar and style checks against the client’s guide, then review gates and a signed approval, with every version kept.
- Grammar and style checks against the client's guide
- Review gates and signed approval
- Every version kept
- 04 · TTS and auto-mix
One voice per client, mixed under the program audio.
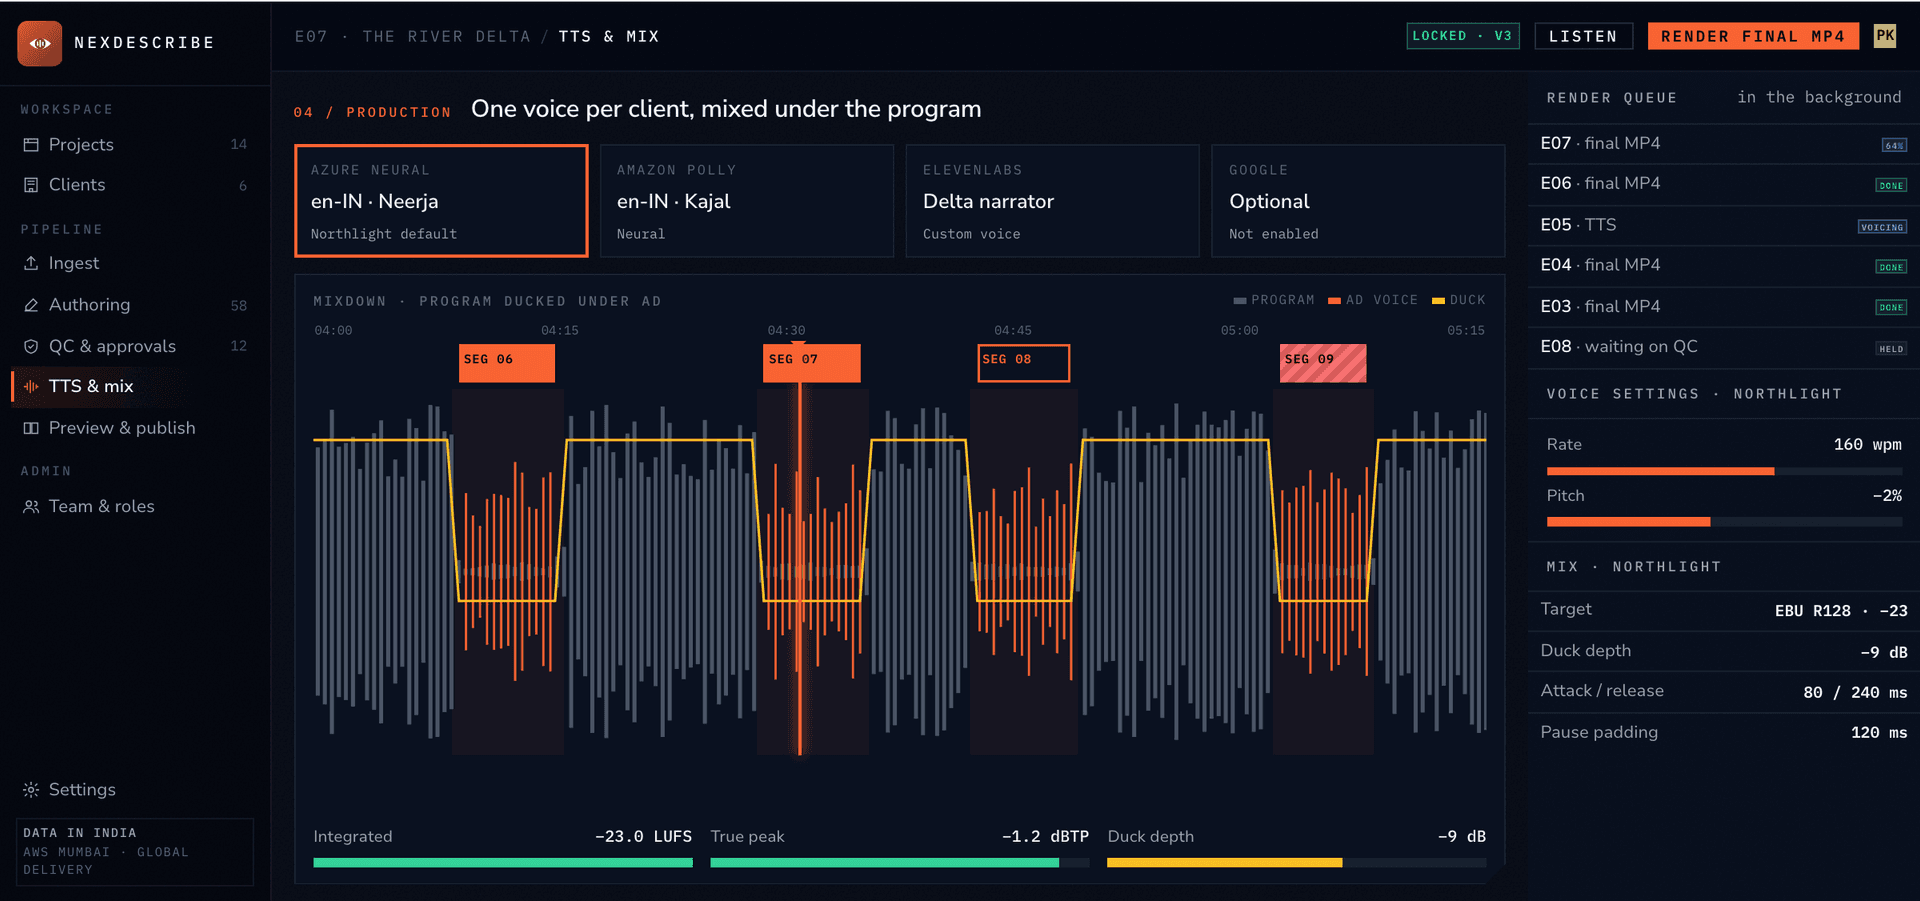
Narration from Azure, Amazon Polly or ElevenLabs with settings held per client, ducked, normalized and mixed into the program audio.
- Azure, Amazon Polly or ElevenLabs narration
- Voice settings held per client
- Ducked and normalized into the mix
- 05 · A/B preview and publish
Hear exactly what the description changed, then ship it.
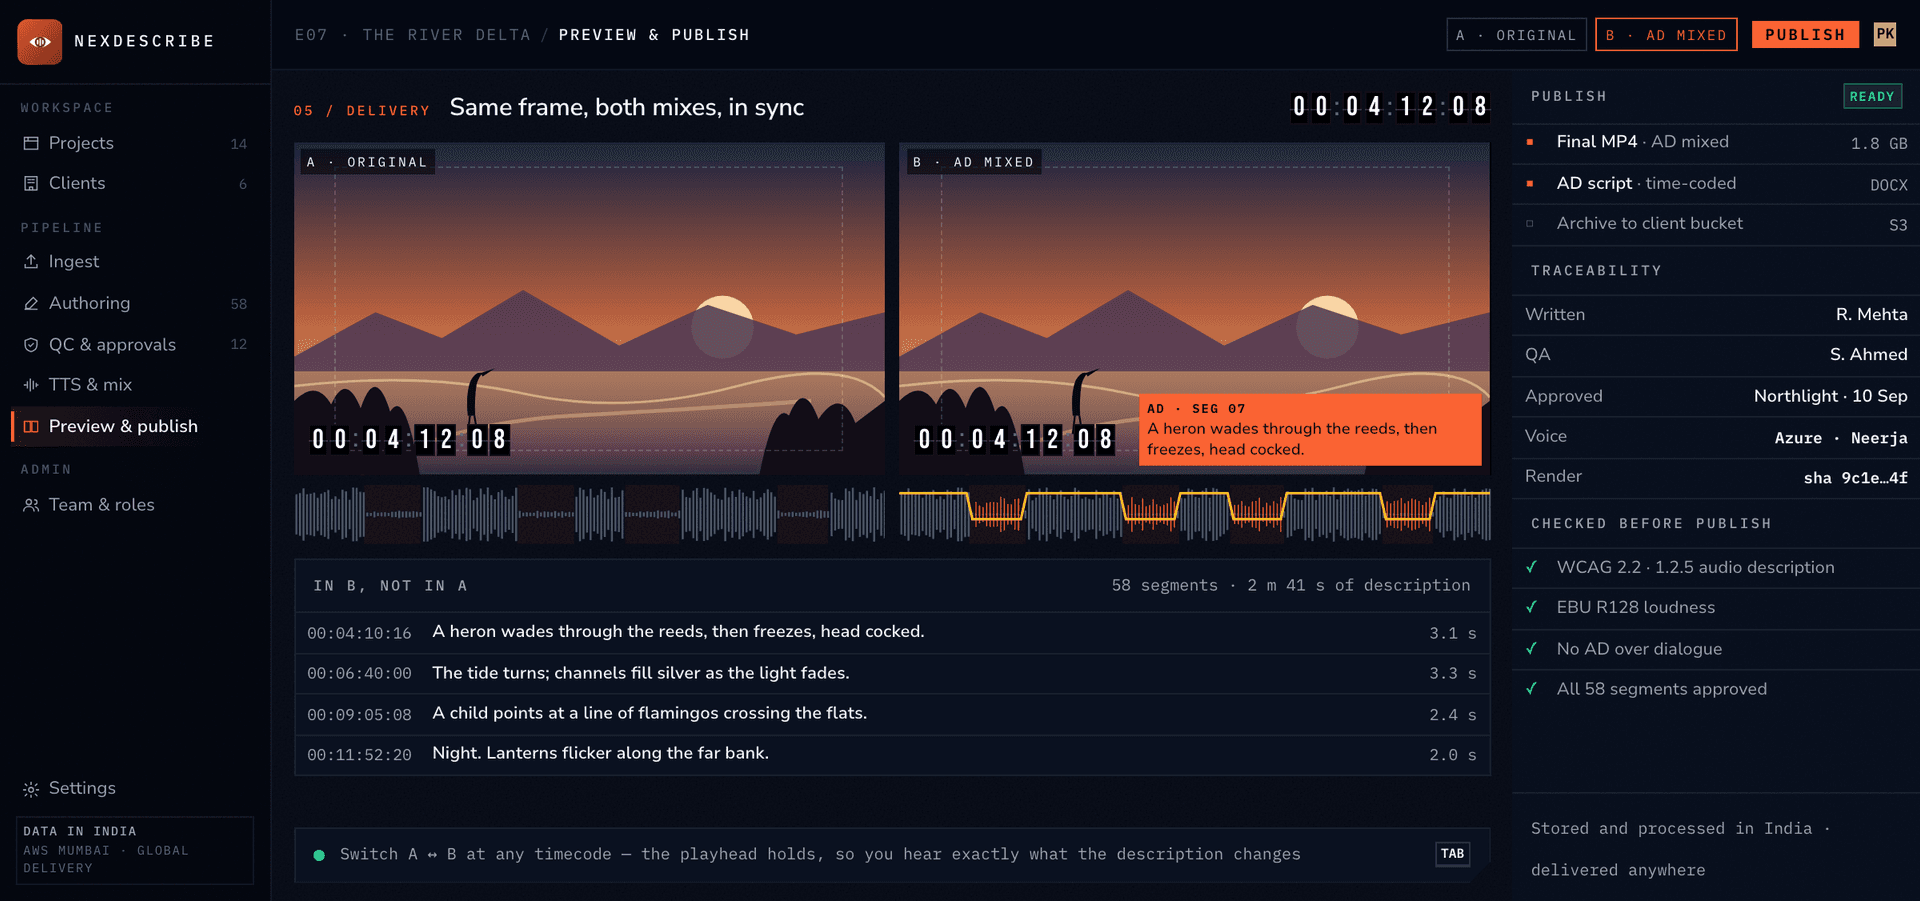
Compare the original against the AD mix in sync, then publish the final MP4 and archive it with who wrote, checked and voiced it.
- Original and AD mix compared in sync
- Final MP4 published
- Who wrote, checked and voiced it, on record
Key features
To the gap
Timed
Description gaps detected in the audio and scripts written to the exact gap, so nothing talks over dialogue.
In the player
Embedded
Standard and extended description tracks embedded in the player, not delivered as separate files nobody plays.
WCAG · ADA
Compliant
WCAG and ADA media requirements met on every asset, with QC sampling by blind and low-vision reviewers.
Human + AI
Hybrid voicing
Professional narrators and AI text-to-speech combined for a consistent tone at catalog volume.
Per asset
Program tracking
Per-asset status, aging and throughput against the deadline, visible to the client.
Questions we get before the first call
See NexDescribe on your own content.
Send a sample and we walk you through a real run, not a slide deck. Product inquiries land with the EdTech team as a tagged lead.